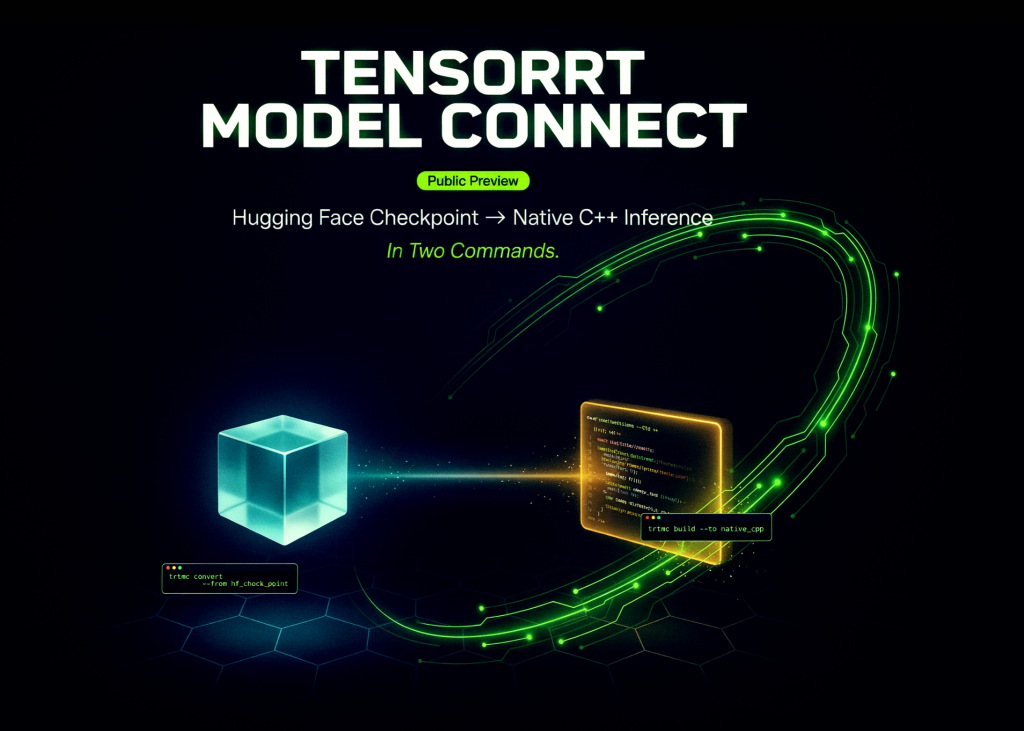
NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in a C++ service, embedded application, or robotics stack without PyTorch in the runtime path. The project is Apache-2.0 licensed and ships as a collection of family-owned reference implementations rather than a single generic converter. NVIDIA also states that the entire project — model implementations, performance tuning, tests, integrations, and docs — was built using OpenAI Codex agents under human direction and review.
Is it deployable?
Yes, for evaluation and native integration work, with real conditions. The code is open and installable. Release wheels currently target Linux aarch64 only, with Python 3.10 or 3.12, glibc 2.39 or newer, and TensorRT 11.1.0.106. x86_64 wheels are not published; x86_64 users must take the Docker source-build path.
- Company level: Best fit today is teams that already own their inference stack: NVIDIA-shop startups, robotics and device companies, and platform or inference teams inside mid-size and large enterprises. Small teams shipping a Python service get less from it. Regulated enterprises should wait for a tagged release before standardizing on it.
- Industries: Robotics and autonomous machines, industrial inspection and manufacturing, automotive in-vehicle compute, medical devices, defense and aerospace edge systems, and media processing — anywhere inference has to live inside a C++ binary rather than a Python server.
- Applications: On-device text generation, speech recognition and synthesis, OCR and document parsing, embeddings and reranking for a retrieval service written in C++, diffusion image and video generation, segmentation, and time-series forecasting.
The two commands
The quick start builds and runs Qwen3-0.6B:
trtmc build Qwen/Qwen3-0.6B –precision bf16 –max-cache-length 16384 –output qwen3-0.6b.bundle
trtmc run ./qwen3-0.6b.bundle –prompt “What is the capital of France? Answer in one word.” –chat-template –no-thinking
The same .bundle loads from C++ with trtmc::load(“./qwen3-0.6b.bundle”).
The bundle is the actual design decision
TRTMC splits build and runtime at a versioned artifact. Python owns checkpoint resolution and TensorRT engine construction. Native profiles then execute inference in C++ without PyTorch. A small number of hybrid profiles invoke a helper Python executable, and their manifests declare that dependency explicitly.
Applications call task APIs — generate(), transcribe(), generate_image(), embed(), solve() — instead of maintaining conversion stages and per-model application glue. trtmc inspect exposes bundle kind, model family, precision, runtime identity, and engines, which makes the artifact auditable rather than opaque.
NVIDIA frames the conventional route as PyTorch → ONNX or TorchScript → TensorRT → model-specific C++ integration, and names the failure modes it removes: export gaps, repeated per-model integration, and validation spread across several conversion artifacts.
Key Takeaways
- Two commands take a supported Hugging Face checkpoint to native C++ TensorRT inference, with no ONNX step.
- A versioned .bundle is the handoff between the Python build and a PyTorch-free C++ runtime.
- The July 29, 2026 GB300 snapshot covers 105 profiles across 76 families; 102 beat their declared reference by more than 5%.
- Wheels are Linux aarch64 only today; x86_64 requires the Docker source build.
Check out the GitHub Repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.