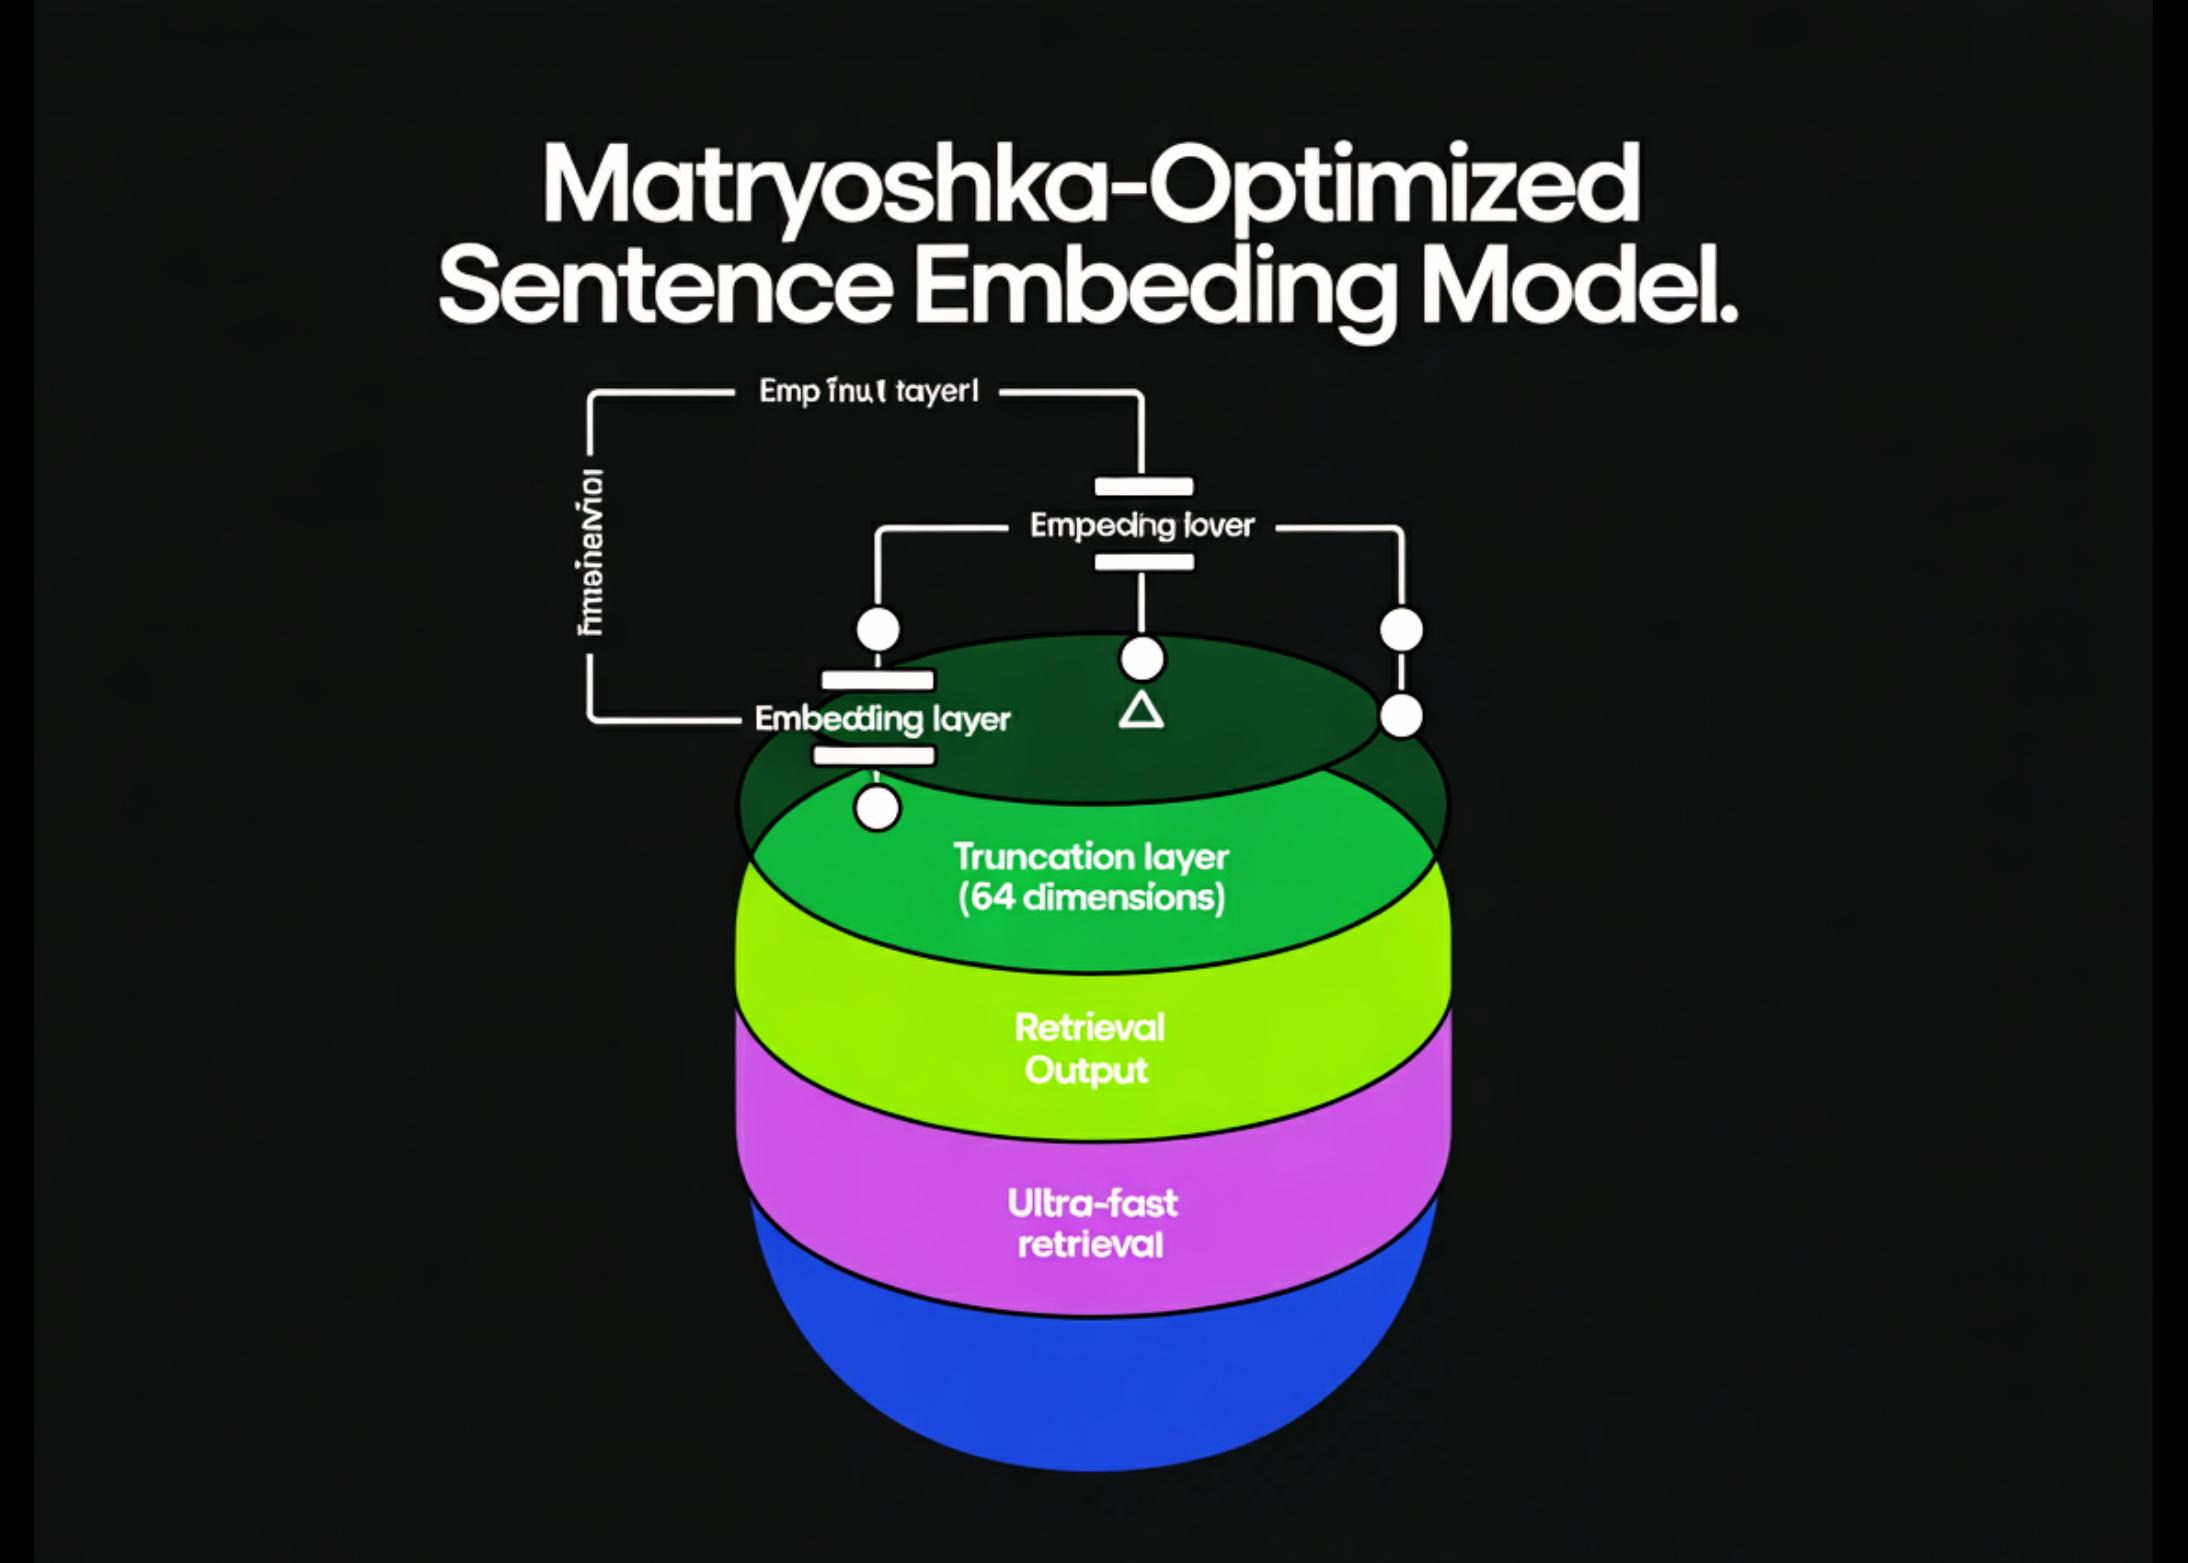
In this tutorial, we fine-tune a Sentence-Transformers embedding model using Matryoshka Representation Learning so that the earliest dimensions of the vector carry the most useful semantic signal. We train with MatryoshkaLoss on triplet data and then validate the key promise of MRL by benchmarking retrieval quality after truncating embeddings to 64, 128, and 256 dimensions. At the end, we save the tuned model and demonstrate how to load it with a small truncate_dim setting for fast and memory-efficient vector search. Check out the FULL CODES here.
import math
import random
import numpy as np
import torch
from datasets import load_dataset
from torch.utils.data import DataLoader
from sentence_transformers import SentenceTransformer, InputExample
from sentence_transformers import losses
from sentence_transformers.util import cos_sim
def set_seed(seed=42):
random.seed(seed)
np.random.seed(seed)
torch.manual_seed(seed)
torch.cuda.manual_seed_all(seed)
set_seed(42)
We install the required libraries and import all the necessary modules for training and evaluation. We set a deterministic seed, so our sampling and training behavior stay consistent across runs. We also ensure PyTorch and CUDA RNGs are aligned when a GPU is available. Check out the FULL CODES here.
def retrieval_metrics_mrr_recall_at_k(
model,
queries,
corpus,
qrels,
dims_list=(64, 128, 256, None),
k=10,
batch_size=64,
):
device = “cuda” if torch.cuda.is_available() else “cpu”
model.to(device)
qids = list(queries.keys())
docids = list(corpus.keys())
q_texts = [queries[qid] for qid in qids]
d_texts = [corpus[did] for did in docids]
q_emb = model.encode(q_texts, batch_size=batch_size, convert_to_tensor=True, normalize_embeddings=True)
d_emb = model.encode(d_texts, batch_size=batch_size, convert_to_tensor=True, normalize_embeddings=True)
results = {}
for dim in dims_list:
if dim is None:
qe = q_emb
de = d_emb
dim_name = “full”
else:
qe = q_emb[:, :dim]
de = d_emb[:, :dim]
dim_name = str(dim)
qe = torch.nn.functional.normalize(qe, p=2, dim=1)
de = torch.nn.functional.normalize(de, p=2, dim=1)
sims = cos_sim(qe, de)
mrr_total = 0.0
recall_total = 0.0
for i, qid in enumerate(qids):
rel = qrels.get(qid, set())
if not rel:
continue
topk = torch.topk(sims[i], k=min(k, sims.shape[1]), largest=True).indices.tolist()
topk_docids = [docids[j] for j in topk]
recall_total += 1.0 if any(d in rel for d in topk_docids) else 0.0
rr = 0.0
for rank, d in enumerate(topk_docids, start=1):
if d in rel:
rr = 1.0 / rank
break
mrr_total += rr
denom = max(1, len(qids))
results[dim_name] = {f”MRR@{k}”: mrr_total / denom, f”Recall@{k}”: recall_total / denom}
return results
def pretty_print(results, title):
print(“\n” + “=” * 80)
print(title)
print(“=” * 80)
for dim, metrics in results.items():
print(f”dim={dim:>4} | ” + ” | “.join([f”{k}={v:.4f}” for k, v in metrics.items()]))
We implement a lightweight retrieval evaluator that encodes queries and documents, computes cosine similarity, and reports MRR@10 and Recall@10. We re-normalize embeddings after truncation so smaller prefixes remain comparable in cosine space. We also added a compact printer to make before/after comparisons easy to read. Check out the FULL CODES here.
SUBSET = “triplet-hard”
SPLIT = “train”
TRAIN_SAMPLES = 4000
EVAL_QUERIES = 300
stream = load_dataset(DATASET_ID, SUBSET, split=SPLIT, streaming=True)
train_examples = []
eval_queries = {}
eval_corpus = {}
eval_qrels = {}
doc_id_counter = 0
qid_counter = 0
for row in stream:
q = (row.get(“query”) or “”).strip()
pos = (row.get(“positive”) or “”).strip()
neg = (row.get(“negative”) or “”).strip()
if not q or not pos or not neg:
continue
train_examples.append(InputExample(texts=[q, pos, neg]))
if len(eval_queries) < EVAL_QUERIES:
qid = f”q{qid_counter}”
qid_counter += 1
pos_id = f”d{doc_id_counter}”; doc_id_counter += 1
neg_id = f”d{doc_id_counter}”; doc_id_counter += 1
eval_queries[qid] = q
eval_corpus[pos_id] = pos
eval_corpus[neg_id] = neg
eval_qrels[qid] = {pos_id}
if len(train_examples) >= TRAIN_SAMPLES and len(eval_queries) >= EVAL_QUERIES:
break
print(len(train_examples), len(eval_queries), len(eval_corpus))
We stream a mined MS MARCO triplet dataset and build both a training set (queries, positives, negatives) and a tiny IR benchmark set. We map each query to a relevant positive document and include a negative document to make retrieval meaningful. We stop early to keep the run Colab-friendly while still large enough to show truncation effects.
device = “cuda” if torch.cuda.is_available() else “cpu”
model = SentenceTransformer(MODEL_ID, device=device)
full_dim = model.get_sentence_embedding_dimension()
baseline = retrieval_metrics_mrr_recall_at_k(
model,
queries=eval_queries,
corpus=eval_corpus,
qrels=eval_qrels,
dims_list=(64, 128, 256, None),
k=10,
)
pretty_print(baseline, “BEFORE”)
We load a strong base embedding model and record its full embedding dimension. We run the baseline evaluation across 64/128/256/full dimensions to see how truncation behaves before any training. We print the results so we can later compare whether MRL improves the early-dimension quality.
epochs = 1
warmup_steps = 100
train_loader = DataLoader(train_examples, batch_size=batch_size, shuffle=True, drop_last=True)
base_loss = losses.MultipleNegativesRankingLoss(model=model)
mrl_dims = [full_dim, 512, 256, 128, 64] if full_dim >= 768 else [full_dim, 256, 128, 64]
mrl_loss = losses.MatryoshkaLoss(
model=model,
loss=base_loss,
matryoshka_dims=mrl_dims
)
model.fit(
train_objectives=[(train_loader, mrl_loss)],
epochs=epochs,
warmup_steps=warmup_steps,
show_progress_bar=True,
)
after = retrieval_metrics_mrr_recall_at_k(
model,
queries=eval_queries,
corpus=eval_corpus,
qrels=eval_qrels,
dims_list=(64, 128, 256, None),
k=10,
)
pretty_print(after, “AFTER”)
out_dir = “mrl-msmarco-demo”
model.save(out_dir)
m64 = SentenceTransformer(out_dir, truncate_dim=64)
emb = m64.encode(
[“what is the liberal arts?”, “liberal arts covers humanities and sciences”],
normalize_embeddings=True
)
print(emb.shape)
We create a MultipleNegativesRankingLoss and wrap it with MatryoshkaLoss using a descending list of target prefix dimensions. We fine-tune the model on the triplets, then re-run the same truncation benchmark to measure the improvement in retention. Also, we save the model and reload it with truncate_dim=64 to confirm practical usage for compact retrieval.
In conclusion, we successfully trained a Matryoshka-optimized embedding model that maintains strong retrieval performance even when we truncate vectors to small prefix dimensions, such as 64. We verified the effect by comparing baseline versus post-training retrieval metrics across multiple truncation sizes and the full embedding. With the saved model and the truncate_dim loading pattern, we now have a clean workflow for building smaller, faster vector indexes while keeping the option to rerank with full-dimensional embeddings.
Check out the FULL CODES here. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.